Qwen3.8 27B Local Model

Near the end of last year, we built an AI Server with two RTX3090 GPU card resulting in 48GB of VRAM. Back then we were running Qwen3 14B model locally on the machine.

Agentic coding 8 months ago was very instructional driven. We would have to concentrate on small tasks and explain the steps in the detail to the AI. There were also many mistakes. For every 5 tasks, there may be bugs based on duplication, syntax errors, misunderstanding, or simply incompetence on behalf of the AI.

How far have we come? Today using the same hardware, we are now running Qwen3.8 27B model. Things are moving very fast. I think since the initial creation of the machine, we have updated the LLM model more than three times, and the vLLM inference serving engine more than four times.

With this current model, we can truly give complex tasks. One major example is that we were unhappy with Perplexica. Its recent release does not perform very well with integrating web search results. We ended up asking the AI to create a new chat application from scratch using an architecture and technology platforms of its choosing. We collaborate with the user interface layout and design.

The final result is stunning. Below is a screenshot of our custom chat application.
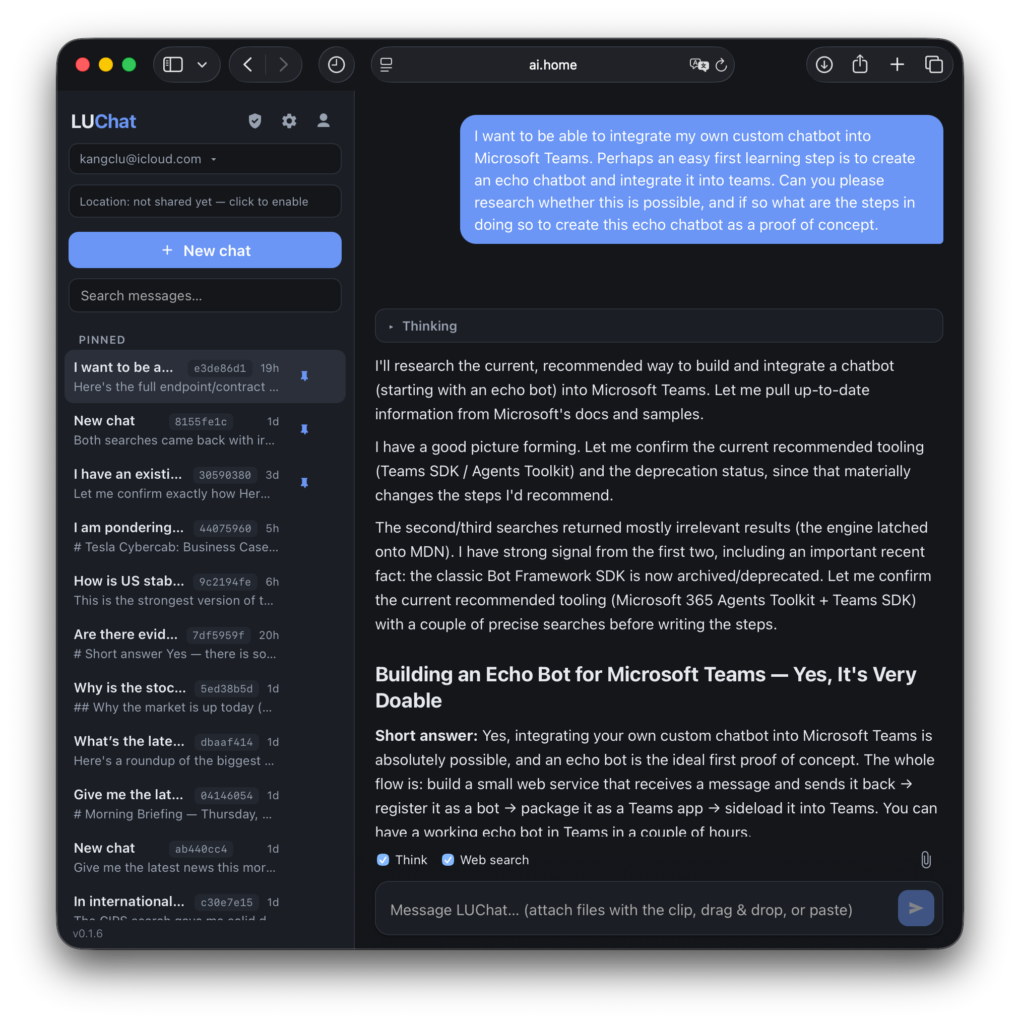
LUChat: Custom Chat Application using Qwen3.8 27B model with integrated web searches and access to our corporate Intranet.

We used very similar steps to install vLLM (v0.28.0 as of this writing):

python3 -m venv .venv
source .venv/bin/activate

pip install torch-c-dlpack-ext
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu130
pip install vllm

We also modified the systemd unit file so that vLLM starts with Qwen3.8 27B model when it boots. The contents of the /etc/systemd/system/vllm.service file is below:

[Unit]
Description=vLLM OpenAI Compatible Server
After=network.target

[Service]
# User and Group to run the service as (e.g., 'youruser', 'yourgroup')
User=kang
Group=kang

# Set the working directory
WorkingDirectory=/home/kang/py_vllm

Environment=CUDA_VISIBLE_DEVICES=0,1

# Need for vLLM 0.27.1
Environment=FLASHINFER_DISABLE_VERSION_CHECK=1

# New recommendation from lued/Qwen3.8-27B-INT8-W8A16-MTP
Environment NCCL_P2P_DISABLE=1
Environment NCCL_CUMEM_ENABLE=0
Environment VLLM_WORKER_MULTIPROC_METHOD=spawn
Environment OMP_NUM_THREADS=1
Environment VLLM_USE_FLASHINFER_SAMPLER=1
Environment PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True,max_split_size_mb:512

# The command to start the vLLM server
# Qwen3.8 27B
ExecStart=/home/kang/py_vllm/.venv/bin/python -m vllm.entrypoints.openai.api_server --model lued/Qwen3.8-27B-INT8-W8A16-MTP \
  --served-model-name Qwen3.8-27B \
  --tensor-parallel-size 2 \
  --pipeline-parallel-size 1 \
  --dtype float16 \
  --performance-mode balanced \
  --max-model-len 262144 \
  --gpu-memory-utilization 0.93 \
  --max-num-seqs 4 \
  --max-num-batched-tokens 4096 \
  --kv-cache-dtype fp8_e4m3 \
  --enable-prefix-caching \
  --enable-chunked-prefill \
  --mamba-cache-mode align \
  --prefix-match-unit 16 \
  --enable-prompt-tokens-details \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_xml \
  --enable-auto-tool-choice \
  --disable-custom-all-reduce \
  --trust-remote-code \
  --default-chat-template-kwargs '{"enable_thinking":true,"preserve_thinking":true}' \
  --override-generation-config '{"temperature":1.0,"top_p":0.95,"top_k":20,"min_p":0.0,"repetition_penalty":1.0,"presence_penalty":0.8}' \
  --speculative-config '{"method":"mtp","num_speculative_tokens":3}' --host 0.0.0.0 --port 8000 --api-key XXXXXXXX

# Restart the service if it fails
Restart=always

[Install]
WantedBy=multi-user.target

We used the opencode.ai harness to build the chat-bot. To configure the harness, below is the ~/.config/opencode/opencode.jsonc:

{
  "$schema": "https://opencode.ai/config.json",
  "permission": {
    "lsp": "allow",
  },
  "provider": {
    "vLLM": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "vLLM (local)",
      "options": {
        "baseURL": "http://0.0.0.0:8000/v1",
        "timeout": false,
        "chunkTimeout": 2400000,
      },
      "models": {
        "Qwen3.8-27B": {
          "name": "Qwen3.8-27B",
          "options": {
            "max_tokens": 262144,
            "max_completion_tokens": 132072,
            "temperature": 1.0,
            "top_p": 0.95,
            "top_k": 20,
            "min_p": 0,
            "presence_penalty": 0.0,
            "repetition_penalty": 1.0,
          },
        },
      },
    },
  },
}

Who would have thought that the first RUST and REACT application that I ended up writing (producing) is one with AI.
Ubuntu 24.04.4 LTS Finally!

In the past few months I have been struggling to upgrade our network attached storage (NAS) server from Ubuntu 22.04 to 22.04. I must have tried more than five times, and each time results in the machine failed to boot and I ended up having to perform a restore which I detailed in this post.

After upgrading the motherboard’s BIOS, I thought I may be in better shape and give the upgrade another shot yesterday. Unfortunately that attempt also failed in the same way.

However, I made two significant discoveries:

  1. The /boot directory contains soft links which pointed to an old kernel that no longer exists. Both files, vmlinuz and initrd.img had stale or invalid links.
  2. The second is that the machine can boot from my backup drive, which was an external SSD drive. For some reason, the upgrade process installed the boot sector on the backup drive.

Today, I tried again. This time I unplugged the backup drive during the upgrade process. I was pretty confident that this will work. BUT it failed again with the same symptoms.

I was at a lost, and decided to consult GROK (the AI). With its help, this is what I ended up doing.

I first totally deleted the boot partition and recreated the partition with the boot flag set. I used the parted command for this.

I then do the following:

# Install the efibootmgr to see boot selection
apt install efibootmgr

# Below is just a sample, actual output will be different
efibootmgr -v
BootCurrent: 0003
Timeout: 1 seconds
BootOrder: 0003,0004
Boot0003* Ubuntu        HD(1,GPT,8fc3aecc-c064-4c3c-a542-ffc866421758,0x800,0x219800)/File(\EFI\UBUNTU\SHIMX64.EFI)
      dp: 04 01 2a 00 01 00 00 00 00 08 00 00 00 00 00 ....
Boot0004* ubuntu        HD(1,GPT,4beb0c04-1f05-4df5-a38a-6a52caba49e2,0x800,0x219800)/File(\EFI\UBUNTU\SHIMX64.EFI)0000424f
      dp: 04 01 2a 00 01 00 00 00 00 08 00 00 00 00 00 ....
    data: 00 00 42 4f

# Mount the root fs and boot partition
mount /dev/nvme1n1p2 /mnt
mount /dev/nvme1n1p1 /mnt/boot/efi

# Mount the required system files in preparation for chroot
for i in /dev /dev/pts /proc /sys /run; do mount -B $i /mnt$i; done
mount -t efivarfs efivarfs /mnt/sys/firmware/efi/efivars
chroot /mnt

# Manually clean up the /boot directory with the bad softlinks
# Reinstall the kernel and the headers (to be doubly sure)
apt update
apt install libproc-processtable-perl
apt install linux-generic linux-headers-generic

# We then force a re-install of grub packages before installing grub
apt install --reinstall grub-efi-amd64 grub-efi-amd64-signed shim-signed
update-initramfs -u -k all
grub-install --target=x86_64-efi --efi-directory=/boot/efi --bootloader-id=ubuntu --recheck
update-grub

# A quick test to see the boot entry exists and everything is in order
efibootmgr -v
exit
 
# Exit and reboot
umount -l /mnt
reboot

I was ecstatic, when the reboot actually worked!

However, there were still a few things that we had to do. The ZFS file system did not come online. I had to import it manually with:

zpool import -a
mount -a

The above resurrected the ZFS file system where ALL of my data resided. I then performed another reboot.

The last issue was that the multipathd.service did not start correctly. Apparently this was due to a library renaming change from 22.04 to 24.04. I had to do this:

sudo ln -s /usr/lib/x86_64-linux-gnu/libaio.so.1t64 \
           /usr/lib/x86_64-linux-gnu/libaio.so.1
ldd /sbin/multipathd   # libaio.so.1 should resolve
sudo systemctl daemon-reload
sudo systemctl start multipathd
sudo systemctl status multipathd

I performed another reboot and the system with all of its services are alive and well.

I then ran into a security issue. The new version 24.04 beefed up the apparmor security behaviour, which resulted in none of my local web sites working. I had to edit the /etc/apparmor.d/local/php-fpm file. The file now contains the following content:

# ZFS site tree used by Apache / PHP-FPM
/mnt/airvideo/ r,
/mnt/airvideo/** r,
/home/kang/log/** rw,

# this app writes/deletes cache files here
/mnt/airvideo/Sites/vault/prod/tmp/ rw,
/mnt/airvideo/Sites/vault/prod/tmp/** rw,
/mnt/airvideo/Sites/vault/dev/tmp/ rw,
/mnt/airvideo/Sites/vault/dev/tmp/** rw,

# ffprobe: inherit the php-fpm profile (ix) so it can read the same media tree
/bin/sh rix,
/bin/dash rix,
/usr/bin/sh rix,
/usr/bin/dash rix,
/usr/bin/zip rix,
/usr/bin/unzip rix,
/usr/bin/ffprobe rix,
/usr/bin/ffmpeg rix,

The above gave php-fpm the ability to read and write certain assets on my file system as well as have the ability to execute certain binaries. I had to activate the above rules with:

sudo apparmor_parser -r /etc/apparmor.d/php-fpm
sudo systemctl reload php8.3-fpm

After all this the server is back up and running. One final sanity test is that I wanted to ensure that this time we actually booted from the right drive.

sudo efibootmgr -v
BootCurrent: 0003
Timeout: 1 seconds
BootOrder: 0003,0004
Boot0003* Ubuntu        HD(1,GPT,8fc3aecc-c064-4c3c-a542-ffc866421758,0x800,0x219800)/File(\EFI\UBUNTU\SHIMX64.EFI)
      dp: 04 01 2a 00...
Boot0004* ubuntu        HD(1,GPT,4beb0c04-1f05-4df5-a38a-6a52caba49e2,0x800,0x219800)/File(\EFI\UBUNTU\SHIMX64.EFI)0000424f
      dp: 04 01 2a 00...
    data: 00 00 42 4f

ls -l /dev/disk/by-partuuid/8fc3aecc*
lrwxrwxrwx 1 root root 15 Aug 28 10:50 /dev/disk/by-partuuid/8fc3aecc-c064-4c3c-a542-ffc866421758 -> ../../nvme1n1p1

We will keep a close eye on it to ensure proper operation. We may not be out of the woods yet.

Homebridge 2.0 and Garage Door Opener

Back in 2017 (more than 9 years ago), I created my own home automation garage door opener using a Raspberry Pi Zero. I then wrote a homebridge plugin so that the garage door opener will work with Homebridge and HomeKit.

The times of change has caught up to us. The original version of the plugin that I wrote with Homebridge was designed and coded for version 1.0. As of May 4, 2026, Homebridge released version 2.0. As of this writing, they are now on version 2.2.1.

Unfortunately for me, this upgrade rendered my old plugin not workable with the latest version of Homebridge. I was going to read the migration guide and performed the changes myself, but of course I was too lazy to get around to it.

Today, I simply asked opencode.ai to tackle this problem. I have attached my opencode session at the end of this post.

I am super surprised that opencode using Qwen 3.6 27B LLM local model running on vLLM handled the changes in a single shot. This was truly a one-shot solution, no fuss, no muss.

I still have to learn that AI can do many things for us and not to short sell it for future potential jobs. Live and learn.

Journey to Ubuntu 24.04 LTS Ended in Another Rescue

My NAS is currently running Ubuntu 22.04.5 LTS. I have tried in the past to perform a do-release-upgrade, and ended up with a system that will not boot.

Since then, I have moved many services away from the NAS. I thought I should give it one more try, and I did just that yesterday. Unfortunately the result ended up the same, resulting another rescue.

I thought I should document the rescue process here again.

# Wipe the root fs
mkfs.ext4 /dev/nvme1n1p2

# Restore from backup
mount /dev/nvme1n1p2 /mnt
mount /dev/backup_partition /mntb
rsync -aAXv /mntb/ /mnt/

# Ensure the root file system new UUID is the same in /etc/fstab
vi /mnt/etc/fstab

# chroot to install the boot partition
mount /dev/nvme1n1p1 /mnt/boot/efi
for i in /dev /dev/pts /proc /sys /run; do mount -B $i /mnt$i; done
mount -t efivarfs efivarfs /mnt/sys/firmware/efi/efivars 
chroot /mnt

# Identify your EFI partition again just in case (e.g., /boot/efi)
sudo grub-install

# Below is more forceful but mostly optional and unnecessary
# grub-install --target=x86_64-efi --efi-directory=/boot/efi --bootloader-id=GRUB --removable --recheck

sudo update-grub
exit

# Exit and reboot
umount -l /mnt
reboot

By now I have become an expert in rescuing failed upgrades with Ubuntu.

I have upgraded my TUF GAMING B550-PLUS motherboard to version 3636. This is a recently released BIOS from ASUS in January of 2026. My previous version of the BIOS was from 2024.

I will give myself another breather, say about a week, before attempting to try again.

Resetting SolarEdge Inverters

In a previous post, one of our two SolarEdge inverters encountered an error and one quick fix is to reset the inverters. This year we had a similar issue.

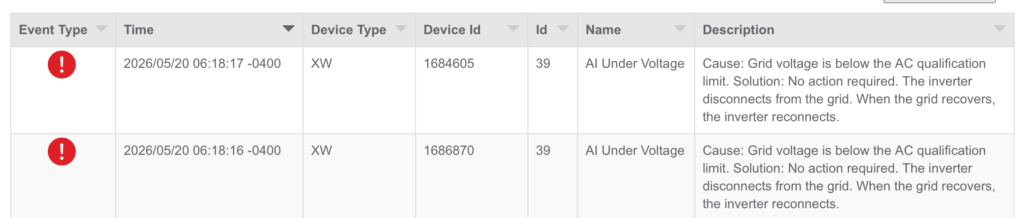
Three days ago, our solar system encountered a grid voltage issue. Our XWPro inverter was in AC PassThru mode causing the SolarEdge inverters to detect the same grid issue. Our solar system is AC coupled. With XWPro handling grid-tied net metering, and battery charging and discharging, and SolarEdge for solar energy generation.

AC Qualification Limit Exceeded

This grid event cause both SolarEdge inverters to go into a “Grid Profile Limit” mode where its AC output was limited to around 100W. When I reset both inverters through the main breaker panel, one recovered while the other continue with the limited output behaviour. To fix the second one, I had to perform a hard reset on the inverter. Below are the steps needed.

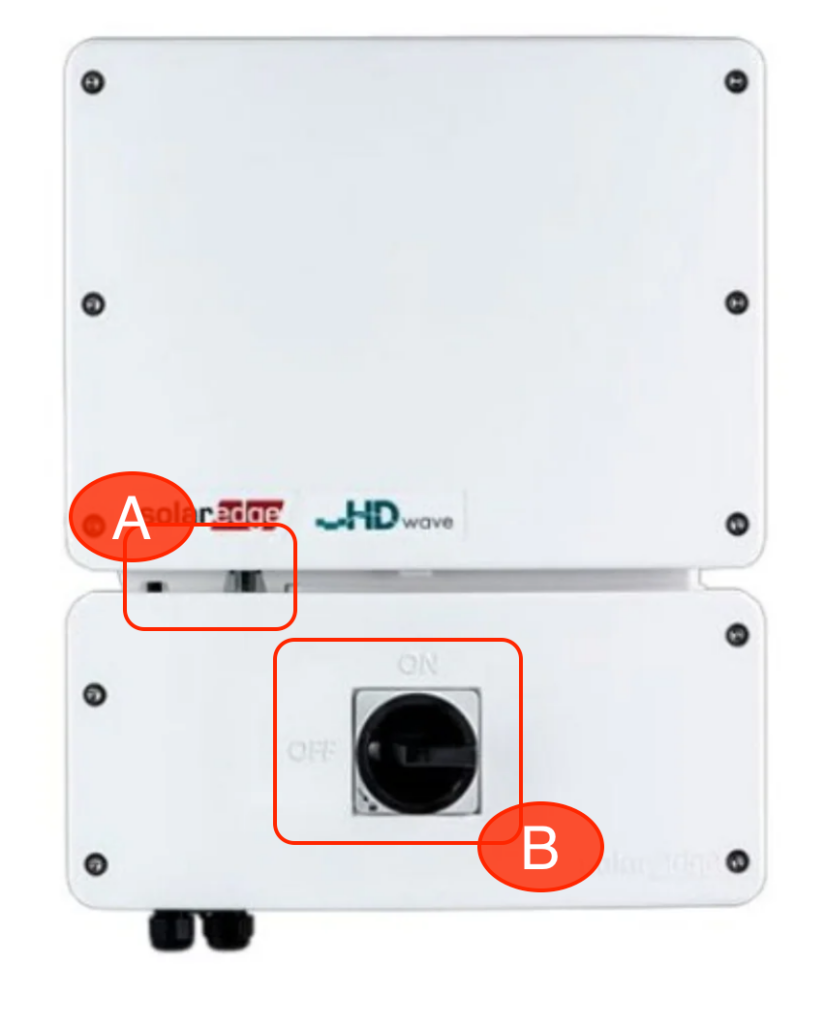
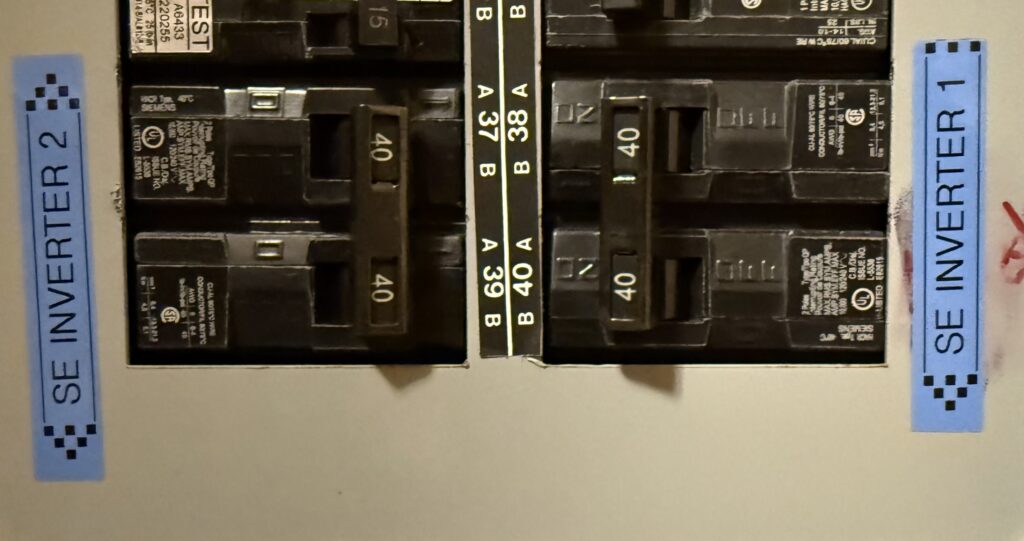
Main Breaker Panel
SolarEdge Inverter Control Positions

First I had to switch off the inverter at position A, and then turn off the DC disconnect at position B. I then had to switch off the breaker on the main panel.

The important part is to wait 5 to 10 minutes to wait for the inverter to discharge for the full reset to happen.

Once the time has passed, perform the action in reverse. Turn back on the breaker, the DC disconnect (B), and then finally turn back on the inverter (A).

Luckily after this hard reset procedure, the second SolarEdge inverter has been fully restored with normal operation.

WebAuthn with Email Implementation

Over the past few years I have developed several services that can be accessed using a web site. Many if not all of these sites require authentication. In the past I have typically adopted a typical user id and password technique, and more recently an email based authentication along with the user’s external IP address, so that they do not need to be burdened with remembering the password.

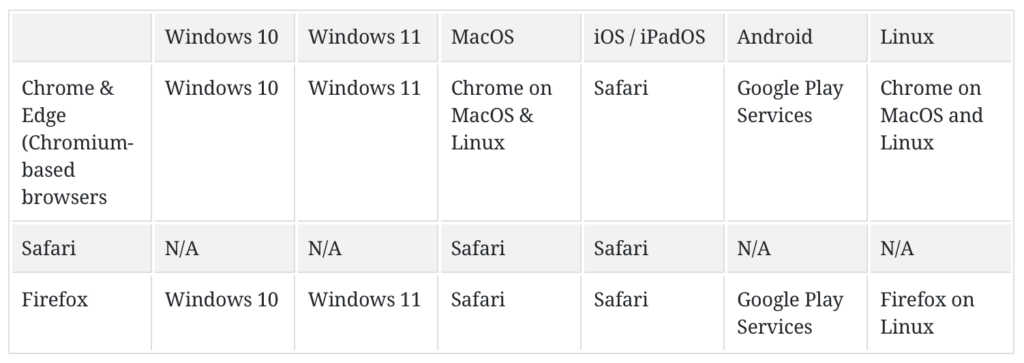
When my iPhone started to adopt the WebAuthn passkey solutions I wanted to make use of this convenient solution for my sites as well. As you can see from the chart below, the adoption across the different platforms and devices are now universal.

Compatibility List

I went about to develop my own identity provider server using the python WebAuthn package. Why did I develop my own solution and instead of using one of the open source solution? I wanted to learn how this works, and what better way to do it than implementing my own version. I also wanted to customize it based on a list of authorized email with the ability to track and manage the access.

This was also the first solution where I used AI to help me vibe code the browser side of the solution. It used the navigator.credentials object to do most of the heavy lifting. The AI generated code at the time is fraught with many errors and bad assumptions which I had fix manually. This was more than a year ago, so I am sure things have improved by now.

In the end, I deployed this custom identity service on auth.lufamily.ca. This custom service also handled the email authentication flow, which goes something like this:

No Email Sent Yes Goto Site Already Registered? Register with Email Read Email and Click on Welcome Login with Email Enter Site

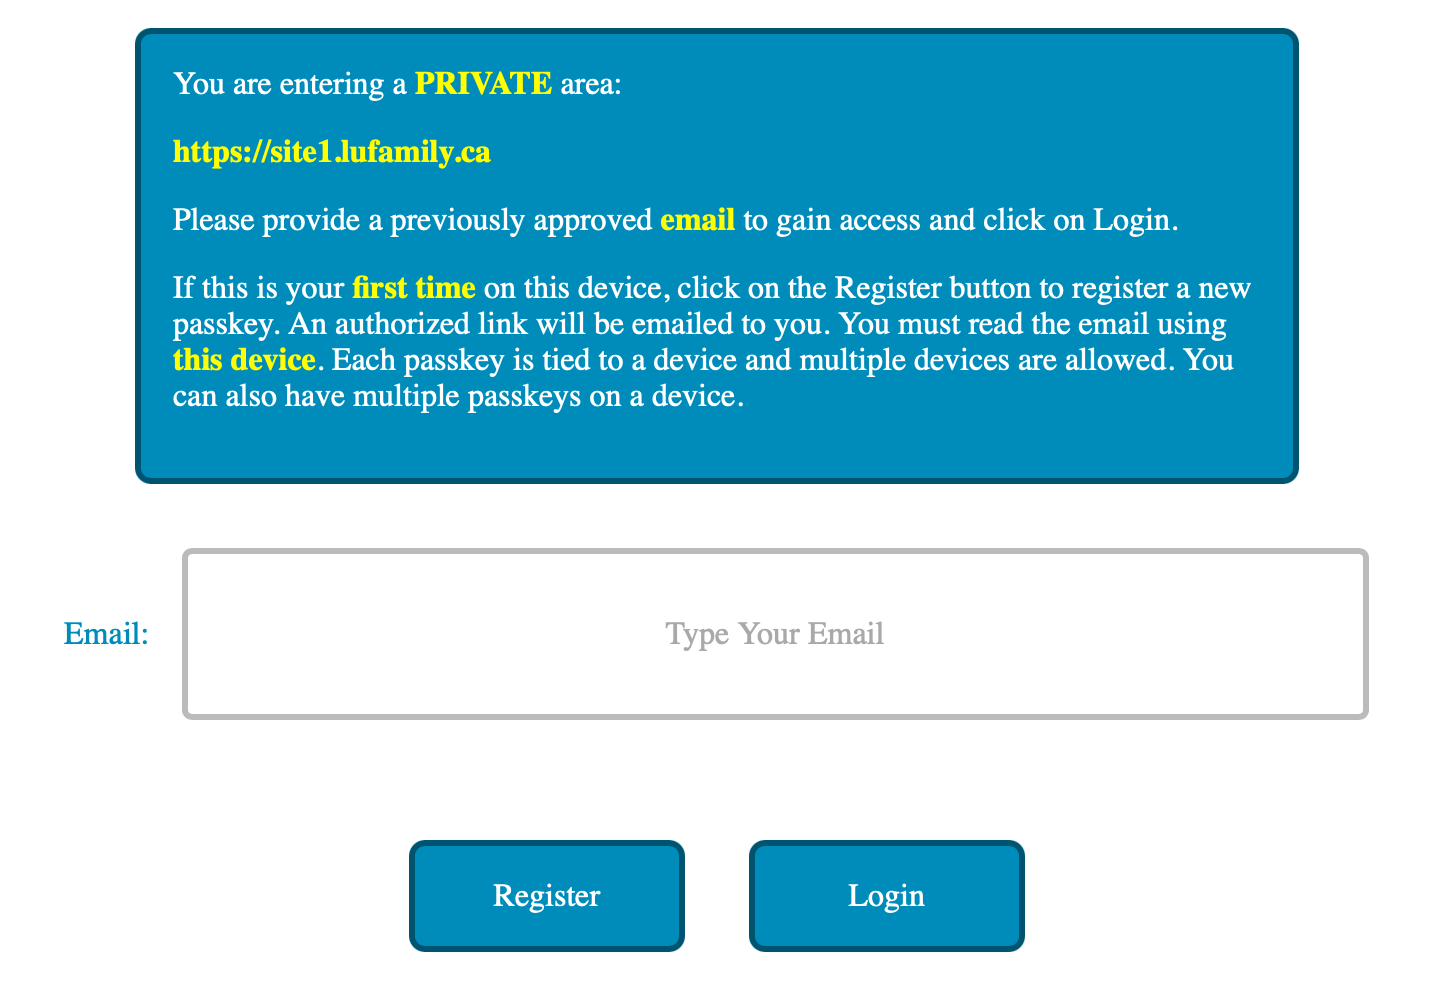
There are no passwords with the above approach. All the users need to remember are the email addresses that they used to register with the site access. The login and registration page looks like this:

Registration and Login Page

For access provisioning, I simply use a JSON file to bind the email address to the allowed web sites. Below is an example:

{
  "jdoe@gmail.com": [
    {
      "user": "John",
      "site": "https://site1.lufamily.ca"
    }
  ],
  "jane.doe@icloud.com": [
    {
      "user": "Jane",
      "site": "https://site1.lufamily.ca"
    },
    {
      "user": "Jane",
      "site": "https://site2.lufamily.ca"
    }
  ]
}

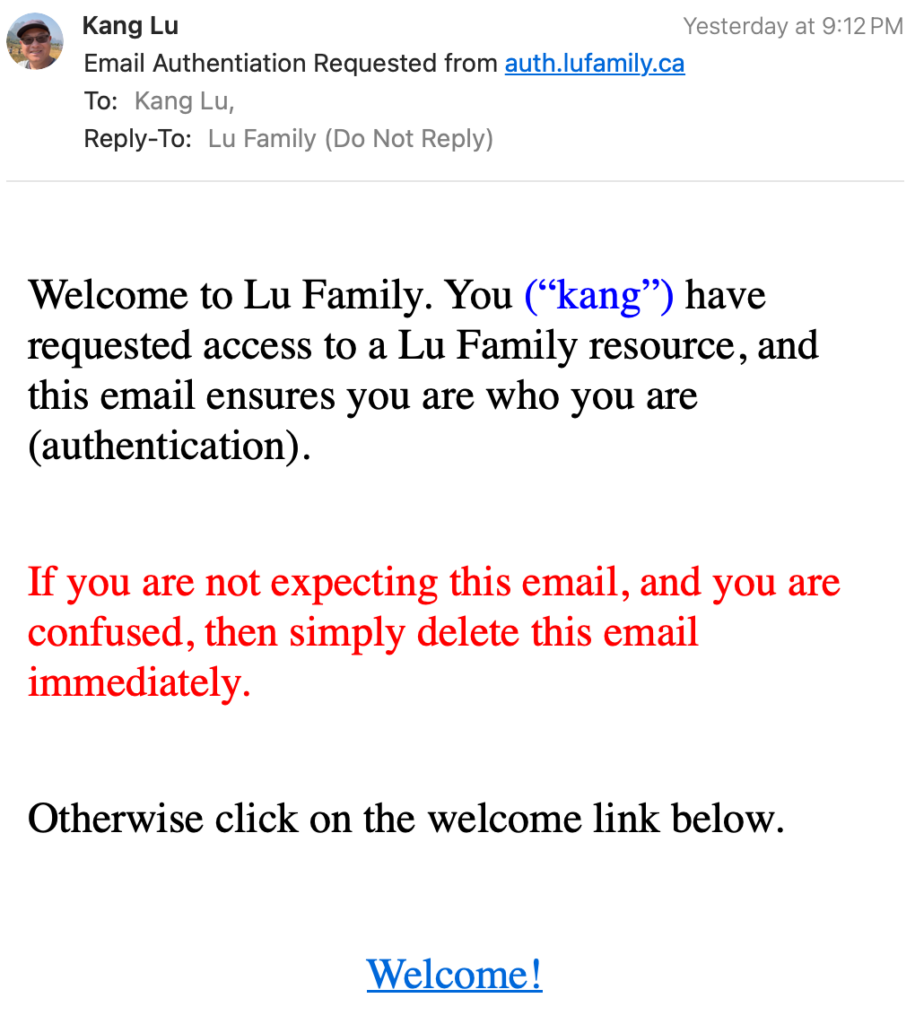
When the user registers, they will receive an email looking like:

Sample onboarding or registration email

In the beginning, I wrote custom code on my web site to use my identity service. However I found out I can write an Apache Lua script to check for token provisioning and invoking of the identity service. I needed some other Lua packages to write my script so I had to figure out which version of Lua is my Apache2 using.

ldd /usr/lib/apache2/modules/mod_lua.so                                                                                                
        linux-vdso.so.1 (0x00007ffd141ea000)
        liblua5.3.so.0 => /lib/x86_64-linux-gnu/liblua5.3.so.0 (0x0000729ff6d47000)
        libcrypt.so.1 => /lib/x86_64-linux-gnu/libcrypt.so.1 (0x0000729ff6d0d000)
        libc.so.6 => /lib/x86_64-linux-gnu/libc.so.6 (0x0000729ff6a00000)
        libm.so.6 => /lib/x86_64-linux-gnu/libm.so.6 (0x0000729ff6919000)
        /lib64/ld-linux-x86-64.so.2 (0x0000729ff6dbe000)

Once I found out that I was using version 5.3, I needed to enable mod_lua with Apache 2:

sudo a2enmod lua

Followed by the installation of three packages that I needed for my script:

sudo luarocks --lua-version 5.3 install lua-cjson
sudo luarocks --lua-version 5.3 install luasec
sudo luarocks --lua-version 5.3 install luasocket

These three packages allow me to process JSON data structures, and communicate with my identity server (auth.lufamily.ca). This way I can add authentication to any sites that I host with Apache2 web server with a virtual host configuration that looks like this:

<VirtualHost *:80>

  <Location / >
    LuaCodeCache forever
    LuaHookAccessChecker /path/to/checkAuthLuFamily.lua handle

    RewriteEngine On

    RewriteCond %{ENV:token} ^$
    RewriteRule ^ https://auth.lufamily.ca/register/%{ENV:cbsite}" [L,R=302]

    Header set Set-Cookie "token=%{token}e; Max-Age=1800; Path=/; HttpOnly; Secure; SameSite=Strict" env=token
  </Location>

</VirtualHost>

The checkAuthLuFamily.lua script is used to check if a token is provided either as an HTTP GET parameter, Authorization Bearer value, or a secure, http-only cookie. The token is actually a JWT token containing user specific attributes derived from the JSON file earlier. This token is provisioned when authentication is successful. If the token is missing, then this means the user has yet to be authenticated so we automatically redirect them to the registration page. If the token is valid, then the script will store a new refreshed token with extended expiry (another 30 minutes) into the environment variable which we use to reset the cookie. Any future requests to the same site will preserve the cookie/token.

I love this flexibility. This means I can add authentication to any site that I host with Apache2 without changing the code or modifying the site. This also means that I can develop future sites and services without having to worry about authentication.

I have not provided the source code here, because I am still testing it, but I wanted to document the concept and the approach, so that I can refer to my own creation in the future.

Replacing Fail Drive in Existing VDEV

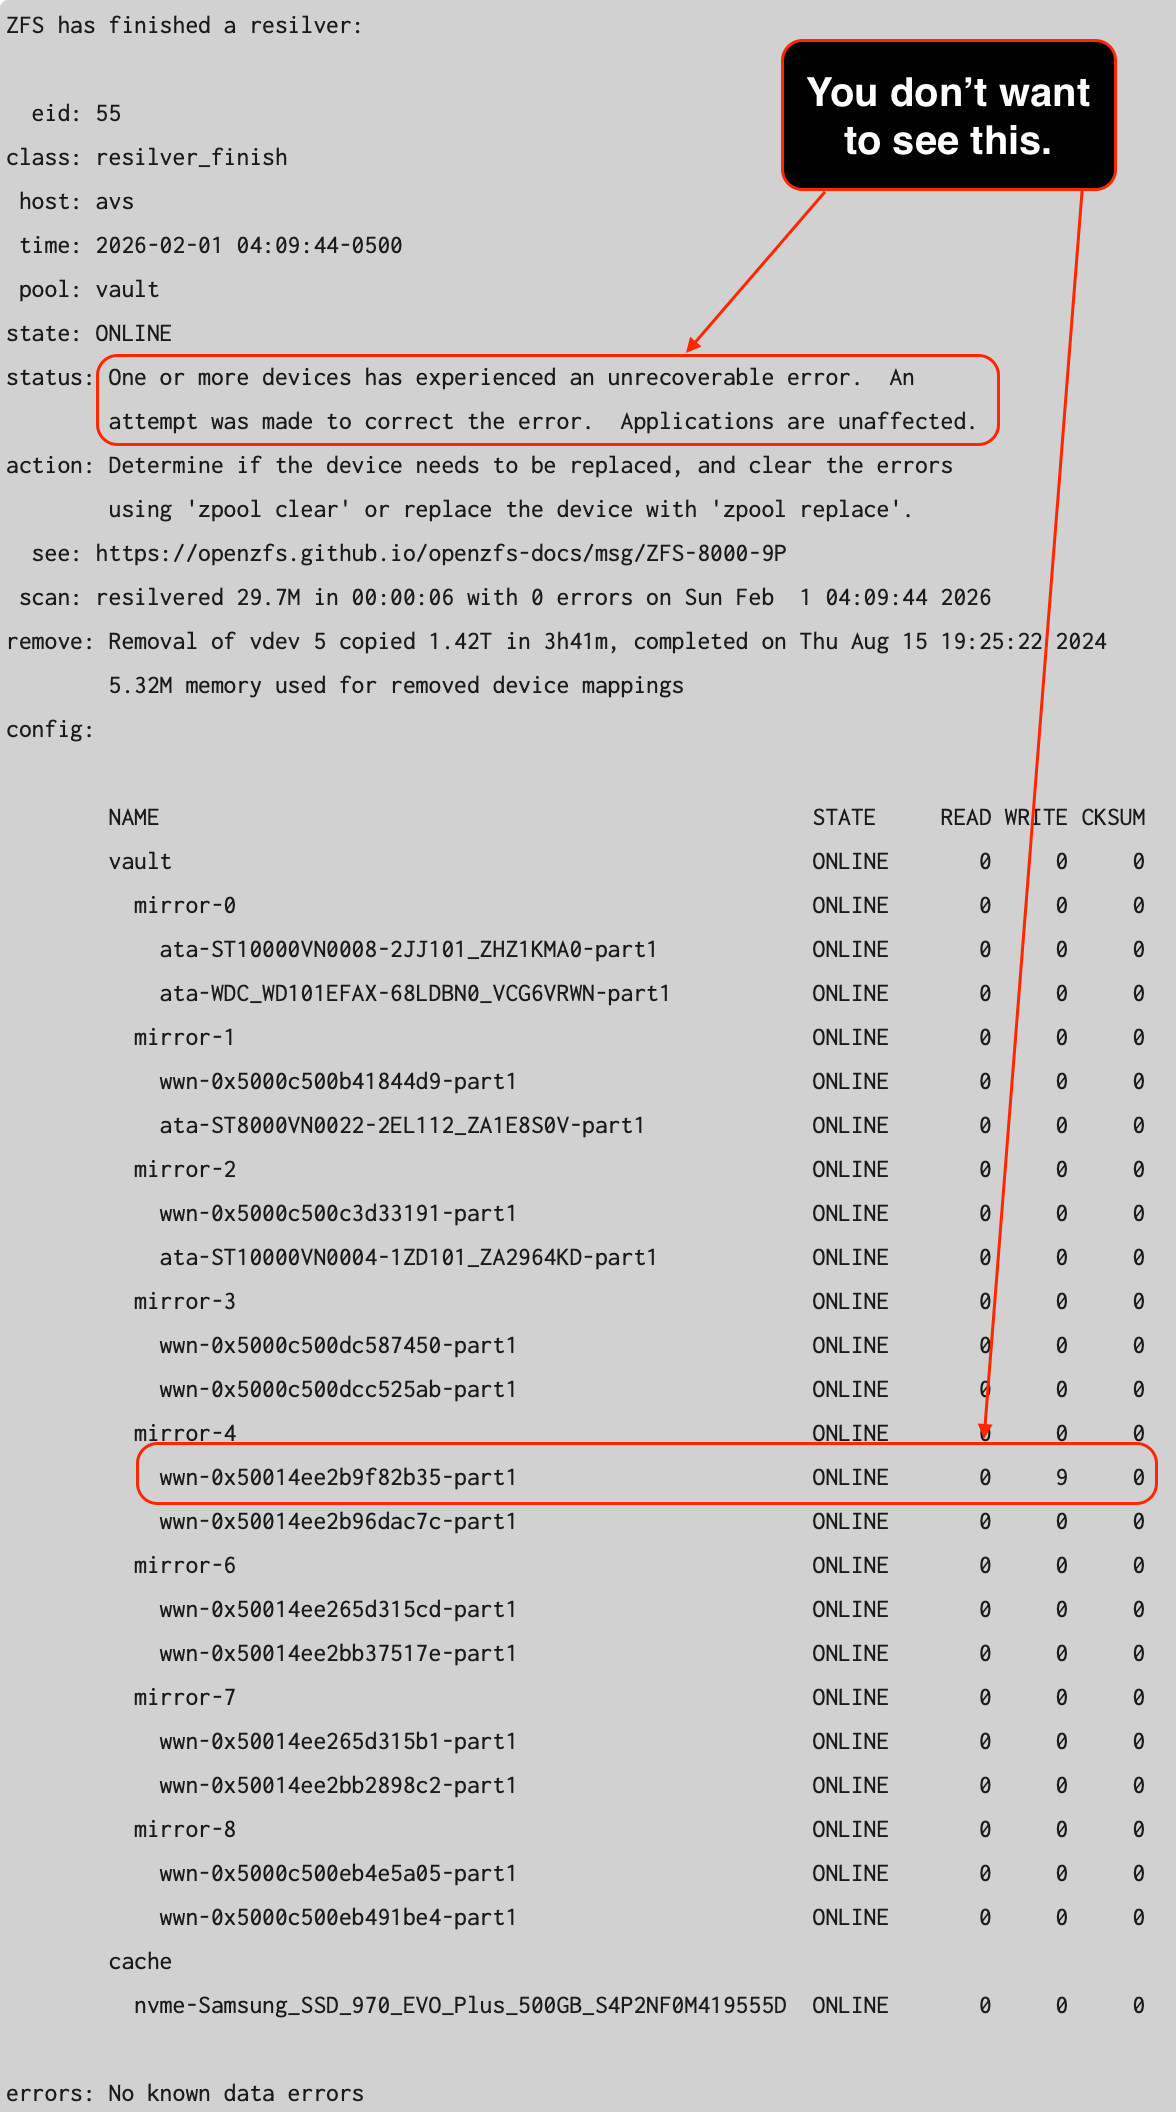
In a previous post, I discussed creating a brand new VDEV with new drives to replace an existing VDEV. However, there is another approach that I chose to use in a very recent event for my NAS (Network Attached Storage) hard drive when it started to encounter write errors and later checksum errors.

The output of zpool status -v

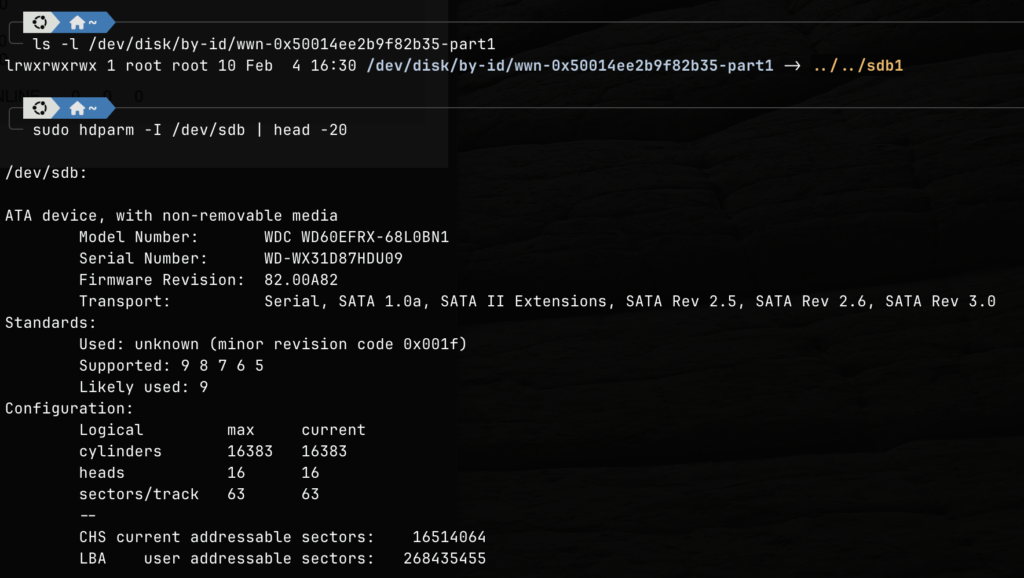
The affected VDEV is mirror-4. Since there are 16 hard drives involved in this storage pool, I had to find out which hard drive is having the issue. I had to perform the following command line operations to obtain the serial numbers of the drives within the VDEV.

Shell commands to get the Serial Number.

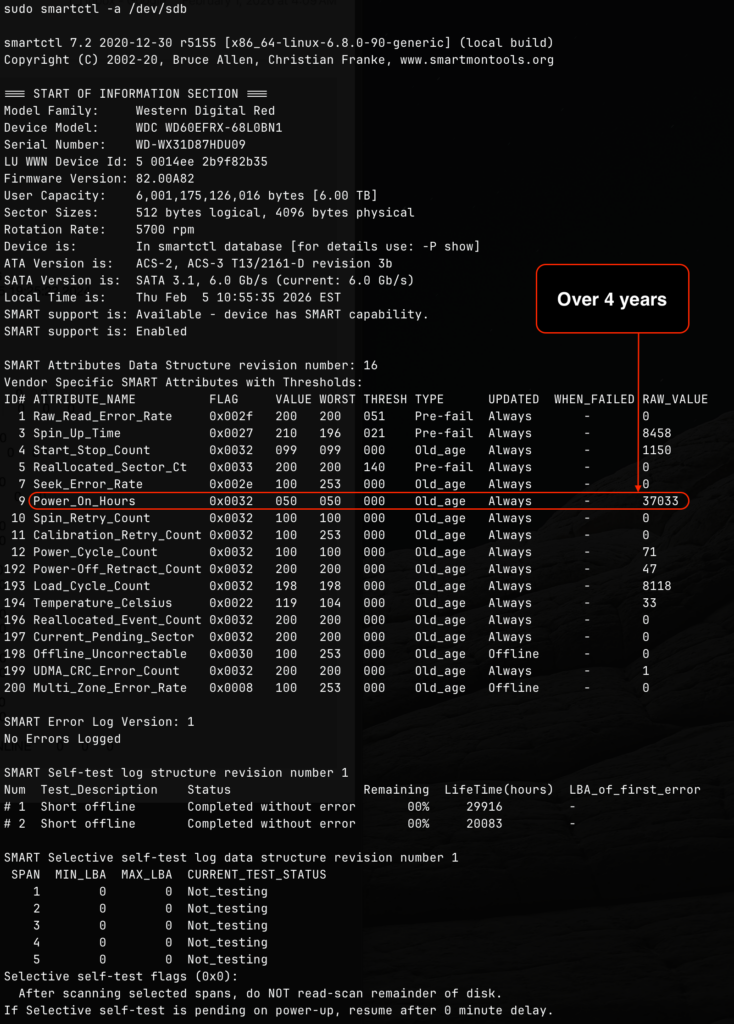
It was the WD60EFRX drive that failed. This is a WD60EFRX Western Digital Red 6TB 5400RPM drive. I was curious to see how old is the drive, so I used the smartctl utility to find out the number of powered on hours that this particular drive endured.

The 4.2 years (37033 / 24 / 365 = 4.2) is well over the 3 years warranty promised by Western Digital, so I took this unfortunate opportunity to get two new Seagate IronWolf Pro 12TB Enterprise NAS Internal HDD Hard Drive. The idea is not just to replace the drive with issue but also to expand the pool, and get an extra 6TB drive from the existing mirror that is still good, and use it as part of my offline backup strategy.

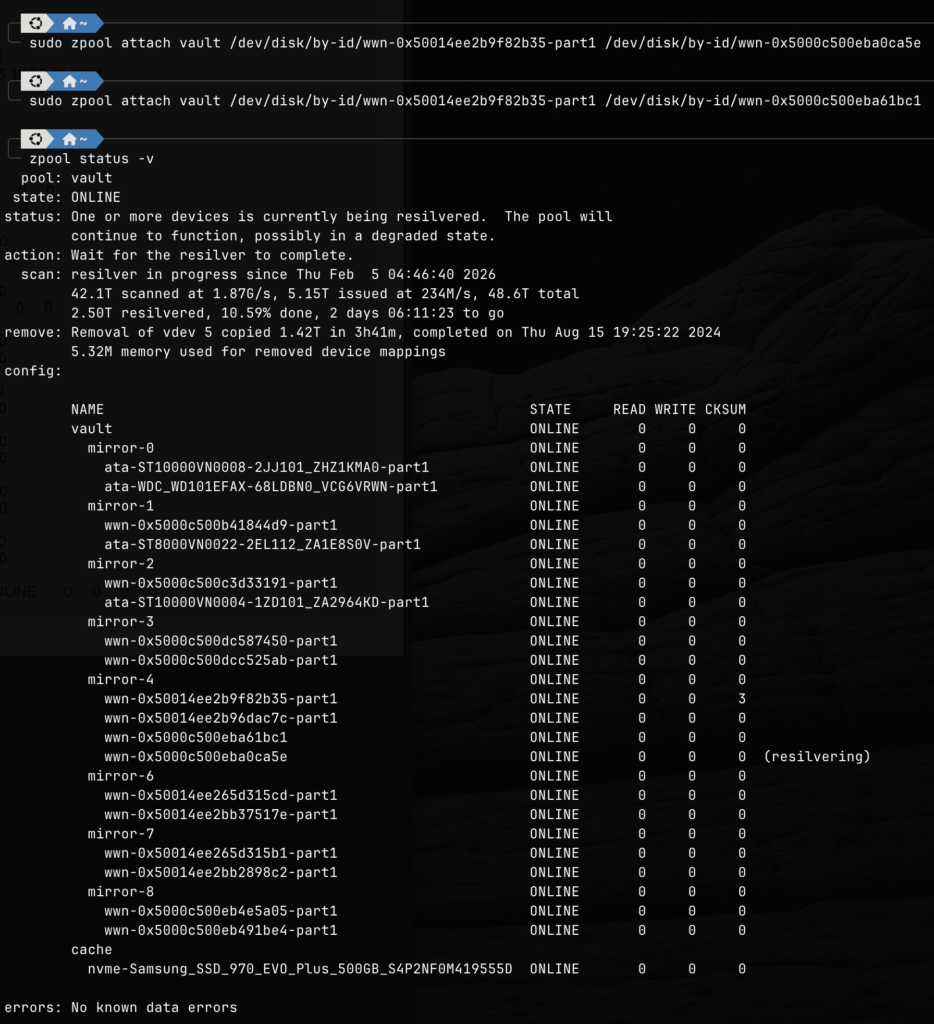
Once the new drives arrived and connected to the system, I simply performed an attach command to add them to the mirror VDEV.

commands to attach the new drive

After attaching the new drives, the zfs pool begins to automatically resilver. The above image was taken several hours after the attachment, and we are now waiting for the last drive to complete its resilvering. Since one of the new drive has already completed its resilvering, this means we have regained full redundancy.

After the resilvering is completed, I will then detach both old drives from the mirror using the detach command.

zpool detach vault /dev/disk/by-id/wwn-0x50014ee2b9f82b35-part1
zpool detach vault /dev/disk/by-id/wwn-0x50014ee2b96dac7c-part1

The first drive will be chucked into the garbage bin, and the second drive will be used for offline backup. Before I use the second drive for offline backup, I need to remove all zfs information and meta data from the drive to avoid any unintentional future conflicts. We do this using the labelclear command like below.

zpool labelclear /dev/disk/by-id/wwn-0x50014ee2b96dac7c

For extra safety, we can also destroy the old partition by using parted and relabeling the disk and create a new partition table. If the above command fails, we can use the dd command to just zero out the first few blocks of the drive.

dd if=/dev/zero of=/dev/disk/by-id/wwn-0x50014ee2b96dac7c bs=1M count=100

In summary, this is the general strategy moving forward. When a drive on my NAS pool starts to fail (before actual failure), I take the opportunity to replace all the drives in the entire mirror with higher capacity drives, and use the remaining good one to serve as offline backup.

Moving My Blog

Since I had difficulties in upgrading my NAS, as I detailed here on this post. I decided that I need to move my NAS services to another server called, workervm. The first service that I decided to move is this web site, my blog, which is a WordPress site hosted by an Apache2 instance with a MySQL database backend.

I decided that instead of installing all the required components on workervm, I will use run WordPress inside a podman container. I already have podman installed and configured for rootless quadlet deployment.

The first step is to backup my entire WordPress document root directory and moved the contents to the target server. I placed the contents on /mnt/hdd/backup on workervm. I also need to perform a dump of the SQL database. On the old blog server, I had to do the following:

sudo mysqldump -u wordpressuser -p wordpress > ../../wordpress.bk.sql

I then proceeded to create the following network, volume, and container files on workervm in ${HOME}/.config/containers/systemd:

I wanted a private network for all WordPress related containers to share and also ensure that DNS requests are resolved properly. Contents of wordpress.network:

[Unit]
Description=Network for WordPress and MariaDB
After=podman-user-wait-network-online.service

[Network]
Label=app=wordpress
NetworkName=wordpress
Subnet=10.100.0.0/16
Gateway=10.100.0.1
DNS=192.168.168.198

[Install]
WantedBy=default.target

I also create three podman volumes. The first is where the database contents will be stored. Contents of wordpress-db.volume:

[Unit]
Description=Volume for WordPress Database

[Volume]
Label=app=wordpress

Contents of wordpress.volume:

[Unit]
Description=Volume for WordPress Site itself

[Volume]
Label=app=wordpress

We also needed a volume to store Apache2 related configurations for WordPress. Contents of wordpress-config.volume:

[Unit]
Description=Volume for WordPress configurations

[Volume]
Label=app=wordpress

Now with the network and volumes configured, lets create our database container with wordpress-db.container:

[Unit]
Description=MariaDB for WordPress

[Container]
Image=docker.io/library/mariadb:10
ContainerName=wordpress-db
Network=wordpress.network
Volume=wordpress-db.volume:/var/lib/mysql:U
# Customize configuration via environment
Environment=MARIADB_DATABASE=wordpress
Environment=MARIADB_USER=wordpressuser
Environment=MARIADB_PASSWORD=################
Environment=MARIADB_RANDOM_ROOT_PASSWORD=1

[Install]
WantedBy=default.target

Note that the above container refers database volume that we configured earlier as well as the network. We are also using the community forked version of MySQL (MariaDB).

Finally we come to the configuration of the WordPress container, wordpress.container:

[Unit]
Description=WordPress Application
# Ensures the DB starts first
Requires=wordpress-db.service
After=wordpress-db.service

[Container]
Image=docker.io/library/wordpress:latest
ContainerName=wordpress-app
Network=wordpress.network
PublishPort=8168:80
Volume=wordpress.volume:/var/www/html:z
Volume=wordpress-config.volume:/etc/apache2:Z
# Customize via Environment
Environment=WORDPRESS_DB_HOST=wordpress-db
Environment=WORDPRESS_DB_USER=wordpressuser
Environment=WORDPRESS_DB_PASSWORD=################
Environment=WORDPRESS_DB_NAME=wordpress

[Install]
WantedBy=default.target

Notice the requirement for the database container to be started first, and this container also uses the same network but the two volumes are different.

We have to refresh the system since we changed the container configurations.

systemctl --user daemon-reload

We can then start the WordPress container with:

systemctl --user start wordpress

Once the container is started, we can check both the WordPress and its database container status with:

systemctl --user status wordpress wordpress-db

And track its log with:

journalctl --user -xefu wordpress

It is now time to restore our old content with:

podman cp /mnt/hdd/backup/. wordpress-app:/var/www/html/

podman unshare chmod -R go-w ${HOME}/.local/share/containers/storage/volumes/systemd-wordpress/_data

podman unshare chown -R 33:33 ${HOME}/.local/share/containers/storage/volumes/systemd-wordpress/_data

The copy will take some time, and once it is completed, we have to fix the permissions and ownerships. Note that both of these have to be performed with podman unshare command so that proper uid and gid mapping can be performed.

I also had to restore the database contents with:

cat wordpress.bk.sql | podman exec -i wordpress-db /usr/bin/mariadb -u wordpressuser --password=############# wordpress

Lastly I needed to modify my main/old Apache server where the port forwarding is directed to so that blog.lufamily.ca requests are forwarded to this new server and port.

Define BlogHostName blog.lufamily.ca
Define DestBlogHostName workervm.localdomain:8168

<VirtualHost *:443>
    ServerName ${BlogHostName}
    ServerAdmin kangclu@gmail.com
    DocumentRoot /mnt/airvideo/Sites/blogFallback
    Include /home/kang/gitwork/apache2config/ssl.lufamily.ca

    SSLProxyEngine  on

    ProxyPreserveHost On
    ProxyRequests Off

    ProxyPass / http://${DestBlogHostName}/
    ProxyPassReverse / http://${DestBlogHostName}/

    # Specifically map the vaultAuth.php to avoid reverse proxy
    RewriteEngine On
    RewriteRule /vaultAuth.php(.*)$ /vaultAuth.php$1 [L]

    ErrorLog ${APACHE_LOG_DIR}/blog-error.log
    CustomLog ${APACHE_LOG_DIR}/blog-access.log combined
</VirtualHost>

Note that on the old server I still have the document root pointed to a fallback directory. In this fallback directory I have php files that I needed to be served directly without being passed to WordPress but the requested path shares the same domain name as my WordPress site. The rewrite rule performs this short circuit processing. When vaultAuth.php is requested, we skip the reverse proxy all together.

This is working quite well. I am actually using the new location of this blog site to write this post. I plan to migrate the other services on my NAS in a similar manner with podman.

The idea is that once the majority of the services have been ported to workervm, then I can reinstall my NAS with a fresh install of Ubuntu 24.04 LTS without doing a migration.

Update 2026-02-28:

I had to move my blog to a different virtual machine because the current one had a network stack corruption. What I found was that the podman volume concept was super handy. I was able to use podman import/export commands to easily move my blog storage and database without having to worry about permissions and other file system nuances.

Rescuing Old MacBook Pro’s

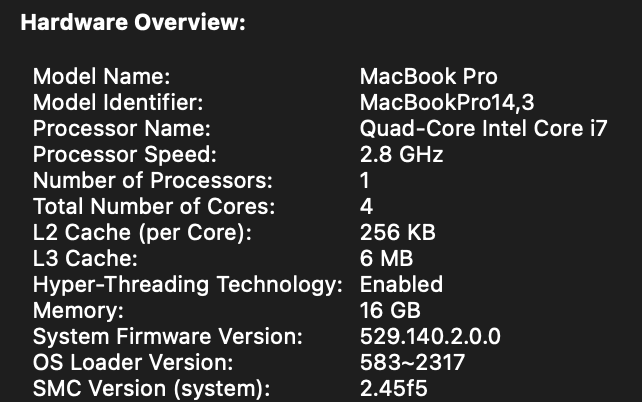
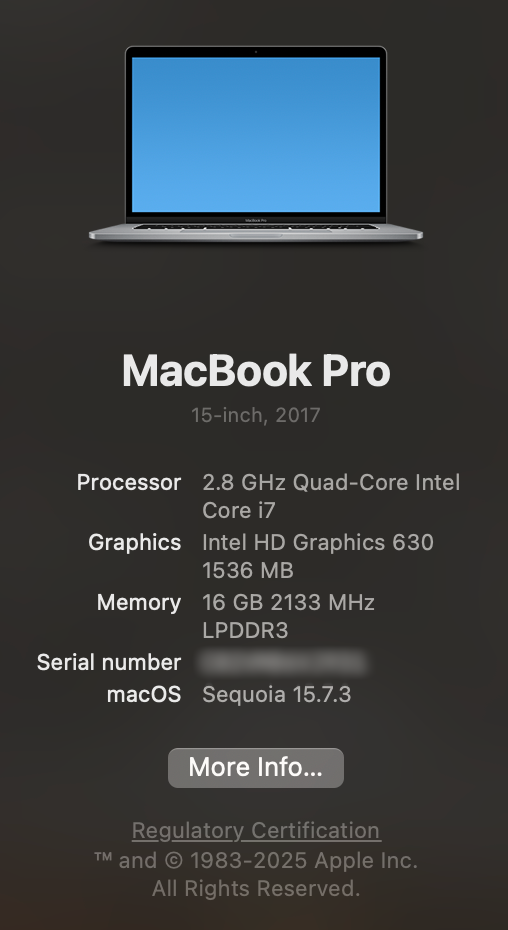
I have a couple of old MacBook Pro’s from late 2016 (MacBook Pro 13,3) and another one from mid 2017 (MacBook Pro 14,3). These laptops have been sitting on my shelves since the pandemic. In 2023 I upgraded them with Sonoma using OpenCore Legacy Patcher (OCLP). I documented the process here. Both of these laptops are Intel based Mac and they have the infamous Touch Bar. These computers are no longer compatible with the most recent macOS. At the time of writing, the latest version is macOS 26 code named Tahoe.

Old laptop hardware spec’s

My original idea in 2026 is to install a suitable Linux distribution. I prepared three distributions:

  • Linux Mint
  • Lubuntu
  • Zorin OS

After several hours of trying these distributions, they all had issues with the Wifi. The driver simply fail to install. A laptop without Wifi is somewhat pointless because you cannot move around with them. Another show stopper with Linux is that we cannot get the Touch Bar to work. At first I didn’t think it was a big deal until I realized that the all important ESC key and all the function keys are on the Touch Bar. Therefore, it is somewhat impractical.

At this point, I was going to chuck them into the e-waste bin, and then I remember that a couple of years ago I played with OCLP. This is a little app that allows you to download a version of macOS installer and create a bootable USB drive with a boot-loader that will make certain firmware adjustments so that an incompatible macOS can be installed on old unsupported hardware, such as these laptops. This time instead of Sonoma, we’ll install Sequoia.

Unfortunately, OCLP still does not support macOS Tahoe, but Sequoia is not too bad. On another Intel based Mac mini, I prepared a bootable USB drive with Sequoia using OCLP, and then I went into the program’s settings to select my targeted Mac model. This allows the program to build and install OpenCore on to the same USB boot drive’s EFI partition.

Once the USB drive is prepared with BOTH the installer and the OpenCore EFI partition with the selected targeted hardware (in our case either MacBook Pro 13,3 or 14,3), we can then use the bootable USB drive on our old MacBooks.

Sequoia on a 2017 MacBook Pro!

The installation process begins with powering on the old MacBook with the USB drive plugged in while holding down the Option key. This will show the current bootable OS that we will be replacing, the EFI partition containing OpenCore, and the new installer that we prepared with macOS Sequoia. We want to select the EFI OpenCore first, and then select the Sequoia Installer. This way the installer will be running with the firmware fixes.

When the installer is running, there will be several reboots. Once the install is completed, there is one last step that we must do. We have to perform a Post Install Root Patch. This effectively replace the OS drivers with old drivers that are compatible with your old hardware.

With the OCLP, I was able to get both laptops to run Sequoia giving an 8 and 9 years old laptop new life. However there are downsides:

  • We cannot perform automated updates from Apple, so I turned off automatic updates and downloads of new OS updates;
  • When OCLP has a new app version, we will need to create a new OpenCore partition installed on the laptop bootable drive’s EFI partition, and we will also have to reapply the root patches;
  • We can only update new OS when they are supported by OCLP, so for Tahoe we will have to await a new version;

I think the disadvantages are negligible when compared to just throwing away the hardware.

I still have a 10+ years old MacBook Air which I look forward to trying with Sequoia.

Ubuntu 22.04 LTS to 24.04 LTS Upgrade Fail

Last Saturday, I decided it was time to switch my NAS server from 22.04 LTS to 24.04 LTS. I’ve been putting it off for ages, worried that the upgrade might not go as planned and something could go wrong. Since 24.04 is already in its fourth point release, I figured the risks should be manageable and it’s time to take the plunge.

I backup my system nightly so the insurance was in place. After performing a final regular update to the system, I started with the following:

sudo apt update && sudo apt upgrade && sudo apt dist-upgrade

I then rebooted the system and executed:

sudo do-release-upgrade

After answering a few questions to save my custom configuration files for different services, it said the upgrade was done. I then rebooted the system, but BOOM! It won’t boot.

The BIOS knows the bootable drive, but when I tried to boot it, it just went back into the BIOS. It didn’t even give me a GRUB prompt or menu.

I figured this wasn’t a big deal, so I booted up the system with the 24.04 LTS Live USB. The plan is to just reinstall GRUB, and hopefully, that will fix the system.

Once I’ve booted into the Live USB and picked English as my language, I can jump into a command shell by pressing ALT-F2. Alternatively, you can press F1 and choose the shell option from the help menu. But, I found that the first method opens up a shell with command line completion, so I went with that.

The boot disk had the following layout (output from both fdisk and parted):

sudo fdisk -l /dev/nvme1n1
Disk /dev/nvme1n1: 931.51 GiB, 1000204886016 bytes, 1953525168 sectors
Disk model: Samsung SSD 980 PRO 1TB
Units: sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disklabel type: gpt
Disk identifier: 90B9F208-2D05-484D-8C8C-B3AE71475167

Device              Start        End    Sectors   Size Type
/dev/nvme1n1p1       2048    2203647    2201600     1G EFI System
/dev/nvme1n1p2    2203648 1921875000 1919671353 915.4G Linux filesystem
/dev/nvme1n1p3 1921875968 1953523711   31647744  15.1G Linux swap

sudo parted /dev/nvme1n1                                                                                                       
GNU Parted 3.4
Using /dev/nvme1n1
Welcome to GNU Parted! Type 'help' to view a list of commands.
(parted) p
Model: Samsung SSD 980 PRO 1TB (nvme)
Disk /dev/nvme1n1: 1000GB
Sector size (logical/physical): 512B/512B
Partition Table: gpt
Disk Flags:

Number  Start   End     Size    File system     Name  Flags
 1      1049kB  1128MB  1127MB  fat32                 boot, esp
 2      1128MB  984GB   983GB   ext4
 3      984GB   1000GB  16.2GB  linux-swap(v1)  swap  swap

As I described in this post, we want to make sure that the first partition is marked for EFI boot. This can be done in parted with:

set 1 boot on
set 1 esp on

I didn’t have to perform the above since the first partition (/dev/nvme1n1p1) is already recognized as EFI System. We also need to ensure that this partition is formatted with FAT32. This can be done with:

sudo mkfs.vfat -F 32 /dev/nvme1n1p1

Since this was already the case, I also did not have to perform this formatting step.

The next step is to mount the root directory and the boot partition.

mount /dev/nvme1n1p2 /mnt
mount /dev/nvme1n1p1 /mnt/boot/efi

We now need to bind certain directories under /mnt in preparation for us to change our root directory to /mnt.

for i in /dev /dev/pts /proc /run; do sudo mount --bind $i /mnt$i; done
mount --rbind /dev /mnt/dev
mount --rbind /sys /mnt/sys
mount --rbind /run /mnt/run
mount -t proc /proc /mnt/proc
chroot /mnt
grub-install --efi-directory=/boot/efi /dev/nvme1n1
update-grub

mount --make-rslave /mnt/dev
umount -R /mnt
exit

If we do not use the –rbind option for /sys, then we may get an EFI error when running grub-install. There are two alternatives that solves the same issue, although used less often, you can also choose one of the following (but not BOTH):

mount --bind /sys/firmware/efi/efivars /mnt/sys/firmware/efi/efivars
mount -t efivarfs none /sys/firmware/efi/efivars

The reinstallation of GRUB did not solve the problem. I had to perform a full system restore using my backup. The backup was created using rsync as described on this post. However, I learned that this backup was done incorrectly! I excluded certain directories using the name instead of /name. This caused more exclusion than intended. The correct method of the backup should be:

sudo rsync --delete \
        --exclude '/dev' \
        --exclude '/proc' \
        --exclude '/sys' \
        --exclude '/tmp' \
        --exclude '/run' \
        --exclude '/mnt' \
        --exclude '/media' \
        --exclude '/cdrom' \
        --exclude 'lost+found' \
        -aAXv / ${BACKUP}

and the restoration command is very similar:

mount /dev/sdt1 /mnt/backup
mount /dev/nvme1n1p2 /mnt/system

sudo rsync --delete \
        --exclude '/dev' \
        --exclude '/proc' \
        --exclude '/sys' \
        --exclude '/tmp' \
        --exclude '/run' \
        --exclude '/mnt' \
        --exclude '/media' \
        --exclude '/cdrom' \
        --exclude 'lost+found' \
        -aAXv /mnt/backup/ /mnt/system/

After the restore, double check that /var/run is soft-linked to /run.

Once the restoration is completed, I follow the above instructions again to re-install GRUB, and I was able to boot back into my boot disk.

Since this upgrade attempt has failed, I now have to figure out a way to move my system forward. I think what I will do is to port all of my services on my NAS as podman root-less quadlets, and then just move the services into a brand new Ubuntu clean installation. This is probably easier to manage in the future.